Experience
Highlights from each role. Happy to share a full CV — reach out onLinkedIn (opens in a new tab)
On this page
BenchSci
London, UK (remote)
Senior Software Engineer, Data
Dec 2024 – present
Integrating heterogeneous biomedical data sources to power data-driven applications and data releases, in a globally distributed, interdisciplinary team.
- Designed and shipped a Python ingestion platform that cut onboarding a new data source from 1–6 weeks to about one week.
- Shipped a knowledge graph release that roughly tripled its association count, fully backward-compatible so no consumer team had to change a query.
Deputy → Acting Engineering Manager, Knowledge Graph & Core Data
May 2025 – Jul 2026
Alongside the engineering role: covered engineering-manager duties for two teams at once — planning, 1:1s, performance and delivery — and managed a cross-team extraction of product data into a standalone pipeline through to its first production run.
- Wrote the brief and OKRs for an ingestion-platform rebuild, negotiated the scope down from a full rewrite, and closed it on time.
- Reintroduced team rituals and cross-team ceremonies, which other teams then adopted as a model.
BenevolentAI
London, UK
Lead Bioinformatics Data Scientist / Squad Lead
Jan 2024 – Dec 2024
Led the team responsible for central data engineering, integrating 80+ internal and external datasets into data releases. Led the redesign of the central ETL framework so any engineer in the company could contribute ETL logic, with data governance built in.
- Line-managed three data engineers, including supporting one into an ML and data science role that matched their interests.
- Coordinated a data contract with the omics data-producing team, governing how their data was produced for the knowledge graph.
Senior Bioinformatics Data Scientist
Jan 2022 – Dec 2023
Data engineering for the biomedical knowledge graph: developed the company's concept and relationship-type ontology and delivered graph updates. Squad Lead from Mar 2023.
- Built Lagoon, a self-serve ingestion framework, and ran the workshops that let data engineers on other teams load data into the central data lake without our help.
- Worked with a cross-functional team to improve drug-target safety assessment, delivering the data that could strengthen it through a new Elasticsearch index.
Advanced Bioinformatics Data Scientist
Nov 2019 – Dec 2021
Data modelling and ETL systems for the knowledge graph behind the company's drug-discovery platform.
- Designed ingestion and data models for sources including multi-omics data, Open Targets and ClinicalTrials.gov, with provenance and revisions built in.
- Ran training workshops that let bioinformaticians and software engineers contribute directly to the knowledge graph.
Aigenpulse
Abingdon, UK
Senior Computational Biologist
Jun 2019 – Oct 2019
Product owner for the CytoML Suite, a cytometry data management and analysis product.
- Designed data workflows that assessed cytometry data quality and informed go/no-go decisions on downstream drug-discovery analysis.
Computational Biologist
Nov 2018 – May 2019
Helped turn bespoke, customer-specific solutions into a scalable SaaS product taking life scientists from raw instrument data to decisions.
- Talked to end users to surface cytometry flow-analysis requirements that had been missed, which were then built into the product.
University of Warwick
Coventry, UK
PhD Researcher, Synthetic Biology
Oct 2014 – Sep 2018
Built software and lab tools to study how microbes share energy by exchanging electrons, as part of the EPSRC & BBSRC-funded Synthetic Biology Centre for Doctoral Training. Thesis: tool development for metabolic analyses in the context of thermodynamic constraints.
- Developed MetQy, an R package published in Bioinformatics that turned KEGG's one-search-at-a-time web tools into bulk, automated analysis of the metabolic functions encoded in over 5,000 genomes.
- Used MetQy to screen genomes for microbes likely to exchange electrons with electrodes, validated the search against known electroactive species, and narrowed roughly 3,500 candidates to 116 testable organism pairings.
- Built a modular anaerobic electrochemistry platform (custom electrodes, 3D-printed parts, wiring and noise shielding) that held strict anaerobic conditions for over three weeks and ran a full 12-cell experiment at once, with four replicates per condition where most published studies use one.
- Ran a 25-day experiment on the platform to test whether a sulphate-reducing bacterium and a methanogen could share energy through a wire: logged current continuously, characterised the electrodes, measured lactate and acetate by ion chromatography, and tracked control-culture growth by daily optical density.
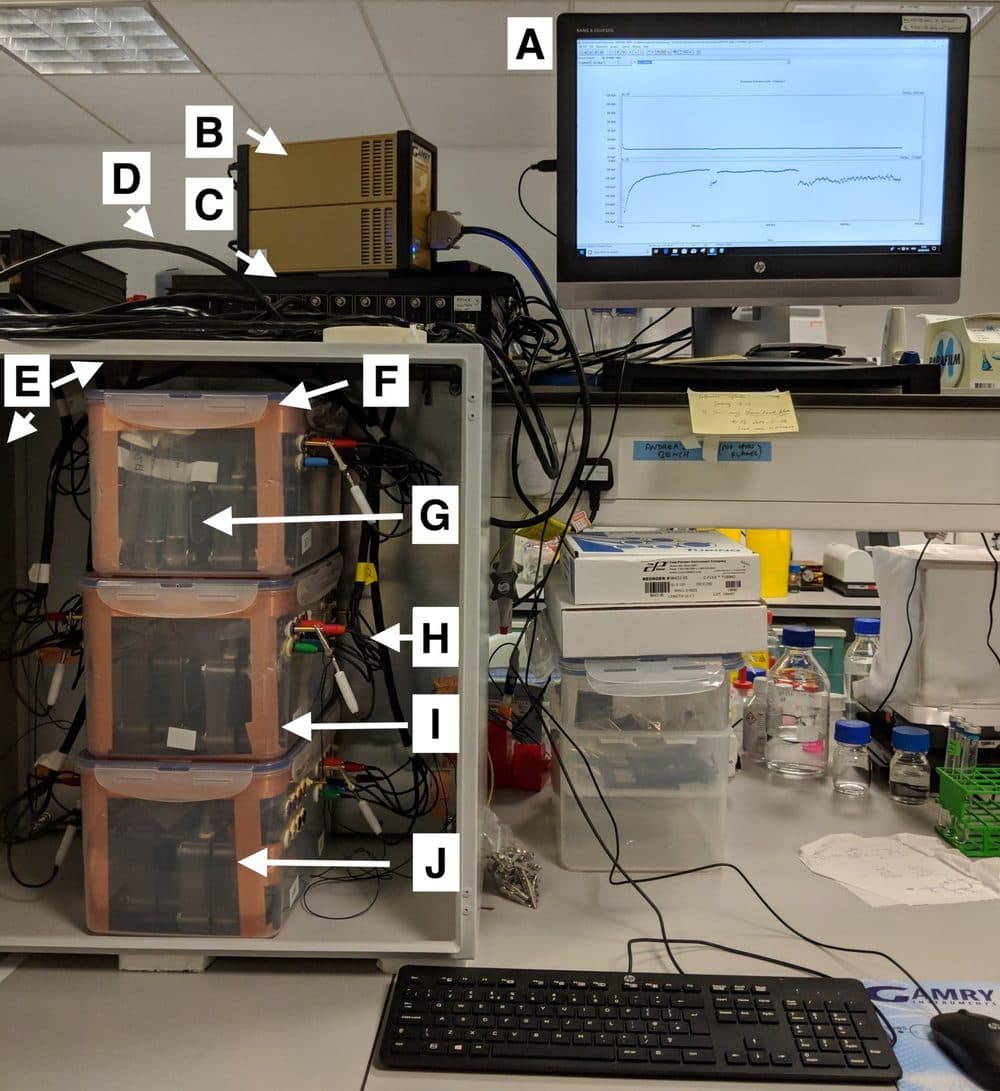
The anaerobic electrochemistry platform: sealed containers of electrochemical cells inside a Faraday cage, wired to a potentiostat and an 8-channel multiplexer. 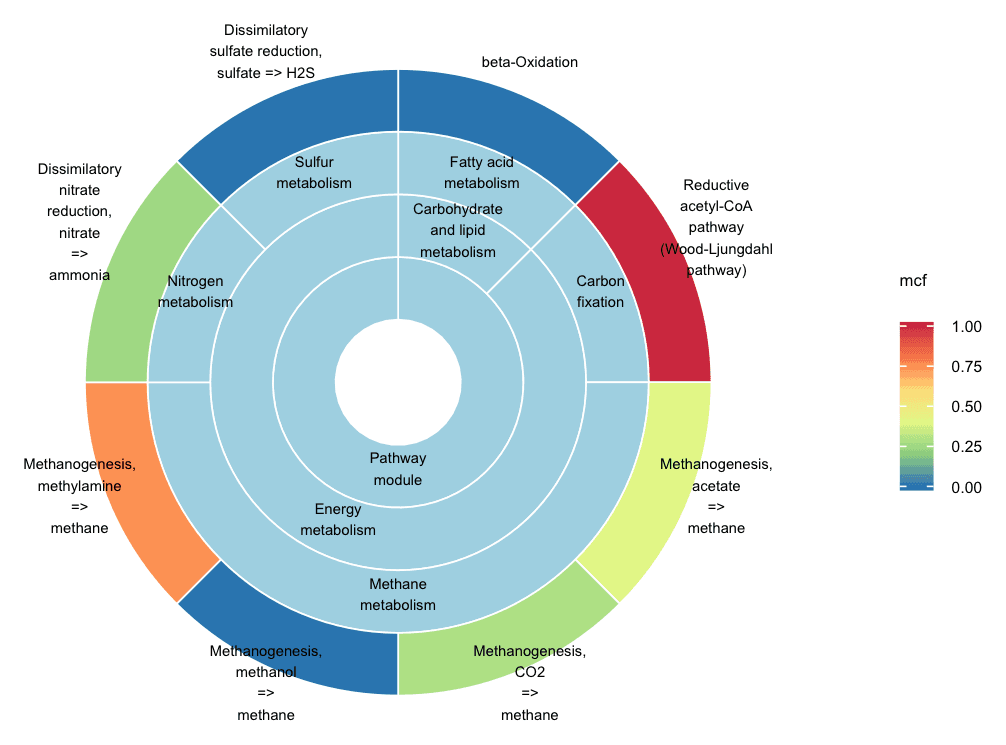
MetQy output: how complete each KEGG metabolic module is in one methanogen's genome, from broad pathway classes (centre) to specific modules (outer ring). Also published in Martinez-Vernon et al. (2018), Bioinformatics.
Projects
Human-in-the-Loop Agentic Résumé Pipeline
Sep 2026 – Oct 2026
Personal project, built with Claude Code as the coding agent.
- Designed and built an open-source, human-in-the-loop agentic pipeline of Claude Code skills and subagents that mines job postings into an evidence-backed skills inventory, walks the candidate through each gap, drafts tailored résumés and critiques them automatically, accepting nothing the model proposes without human confirmation.
- Created an interactive public demo that showcases the pipeline end to end on fictional personas: visitors approve, edit or reject each AI-proposed step, from CV to skills inventory to gap analysis to tailored résumé.
Try the demoRead the case studySee the repo on GitHub (opens in a new tab)
Skills and tools
- Programming languages
- Python, SQL, PySpark, R, Java, Bash
- Data pipelines
- Apache Airflow, Prefect, Apache Beam, Argo Workflows, Databricks, BigQuery
- Knowledge graphs
- Neo4j, SPARQL, RDF, OWL, LinkML, biomedical ontologies
- Cloud and infrastructure
- Google Cloud, AWS, Kubernetes, Docker, Terraform
- AI
- Retrieval-augmented generation, Claude API, agentic development workflows
- Practices
- Release management, privacy and compliance engineering, FAIR data
- Leadership
- Engineering management, technical leadership, stakeholder management, mentoring
- Spoken languages
- Spanish (native), English (proficient), German (intermediate)
Education
PhD, Synthetic Biology
University of Warwick, UK · 2014 – 2019 (awarded Feb 2019)
MSc, Systems Biology (Distinction)
University of Warwick, UK · 2013 – 2014
BSc (Hons), Biotechnology
Universidad Autónoma de Querétaro, Mexico · 2008 – 2012
Selected publications
- Martinez-Vernon et al. (2018). MetQy – an R package to query metabolic functions of genes and genomes. Bioinformatics, 34(23).
- Martinez-Vernon et al. (2018). An improved machine learning pipeline for urinary volatiles disease detection: Diagnosing diabetes. PLoS ONE, 13(9): e0204425.
- Sasidharan, Martinez-Vernon, et al. (2018). A low-cost DIY device for high resolution, continuous measurement of microbial growth dynamics. bioRxiv preprint.